Cloud GPU prices for AI images and video
A cloud GPU is a graphics card in someone else’s data centre that you rent by the hour to run AI models. VRAM, the card’s own memory, decides which models fit.
Of eight GPU clouds read on 24 October 2026, Runpod’s Community Cloud lists the lowest rate for an RTX 4090, at $0.34 an hour. Its H100 PCIe, at $1.99, is the lowest by one cent.
Vast.ai’s cheapest verified hosts undercut every list price on the 5090, L40S, A100 and RTX PRO 6000. Its RTX PRO 6000 is $1.08 against Runpod’s $1.69. Vast.ai figures count its verified hosts only.
On our own Runpod account on 17 October 2026, one 1280 x 1280 FLUX 3 Klein image took about 28.5 seconds on a Secure Cloud RTX 4090. At that tier’s rate it costs $0.007 of GPU time an image.
| Provider and tier | RTX 4090 (24 GB) | RTX 5090 (32 GB) | L40S (48 GB) | A100 (80 GB) | H100 (80 GB) | RTX PRO 6000 (96 GB) |
|---|---|---|---|---|---|---|
| Runpod Community Cloud List price; A100 SXM, H100 PCIe | $0.34 | $0.69 | $0.79 | $1.39 | $1.99 | $1.69 |
| Runpod Secure Cloud List price; A100 SXM, H100 PCIe | $0.89 | $1.19 | $1.09 | $1.79 | $2.89 | $2.49 |
| Runpod Serverless Flex worker, runs only on a request | $1.10 | $1.58 | $1.75 | $2.72 | $4.79 | $3.49 |
| Vast.ai, lowest verified Marketplace; H100 PCIe, RTX PRO 6000 WS | $0.41 | $0.64 | $0.74 | $1.07 | $2.00 | $1.08 |
| Vast.ai, median verified Marketplace; the middle offer | $0.67 | $1.03 | $0.80 | $1.12 | $2.33 | $1.83 |
| TensorDock Typical price, varies by host; A100 PCIe, H100 SXM5 | $0.35 | Not listed | Not listed | $1.50 | $2.25 | Not listed |
| Massed Compute List price; H100 80 GB | Not listed | Not listed | $0.97 | $1.35 | $2.73 | $2.19 |
| Modal Per-second rate times 3,600; H100 SXM5 | Not listed | Not listed | $1.95 | $2.50 | $3.95 | $3.03 |
| Lambda List price; H100 PCIe | Not listed | Not listed | Not listed | Not listed | $3.29 | Not listed |
| DigitalOcean GPU Droplets List price; HGX H100 | Not listed | Not listed | $1.57 | Not listed | $4.41 | Not listed |
| Paperspace On-demand promo price | Not listed | Not listed | Not listed | Not listed | $5.95 | Not listed |
Scroll sideways for all 7 columns
Why the same H100 costs three times more across clouds
The spread comes from who owns the machine and how long you commit. An H100 runs from $1.99 an hour on Runpod’s Community Cloud to $5.95 on Paperspace on demand.
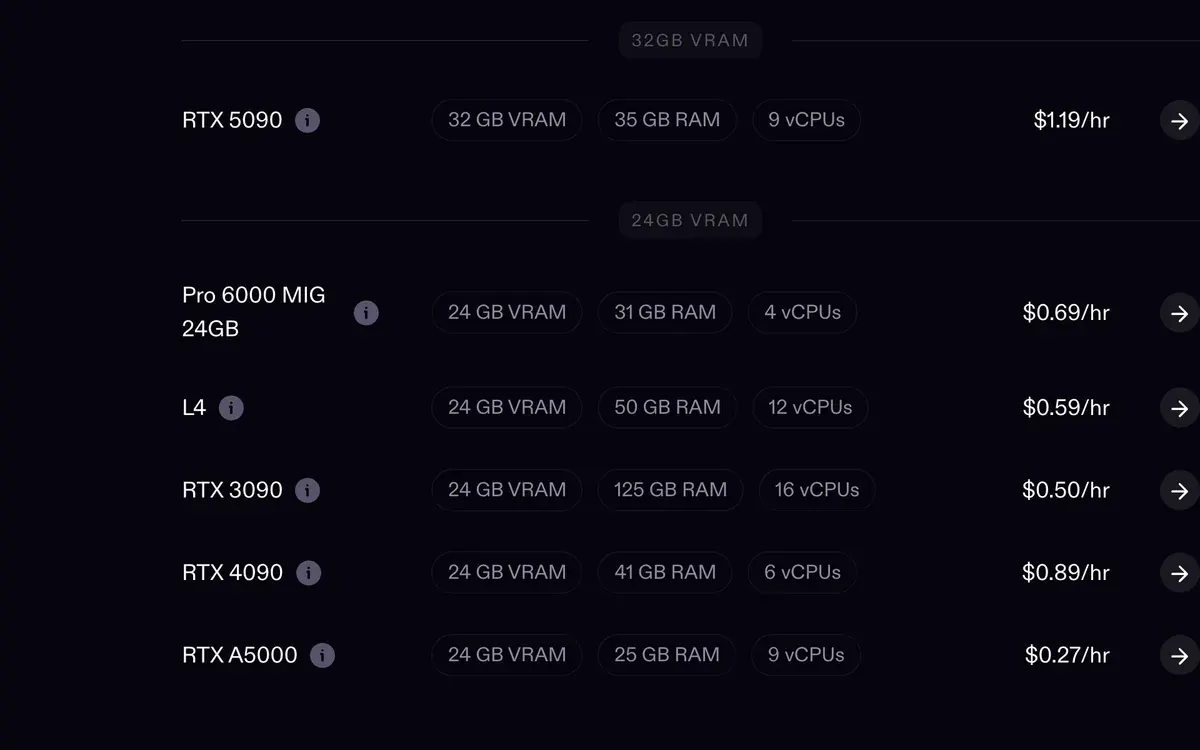
Runpod’s Community Cloud and Vast.ai rent machines owned by third-party hosts. Runpod’s Choose a Pod docs rate Community Cloud reliability as “Variable”, and Runpod no longer accepts new Community hosts.

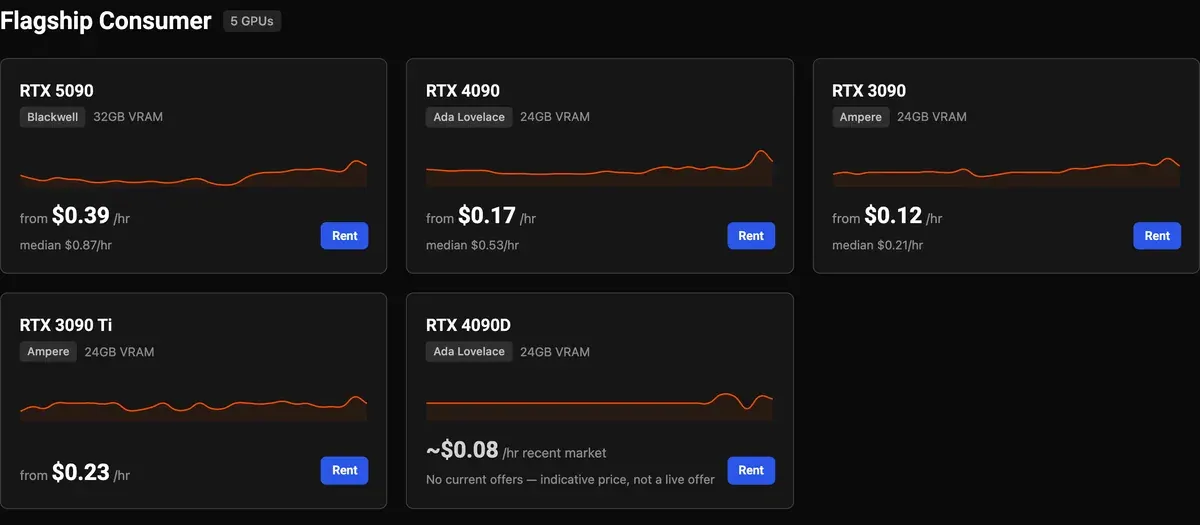
Vast.ai’s hosts set their own prices: its 39 verified RTX 4090 offers ran from $0.41 to a middle price of $0.67.
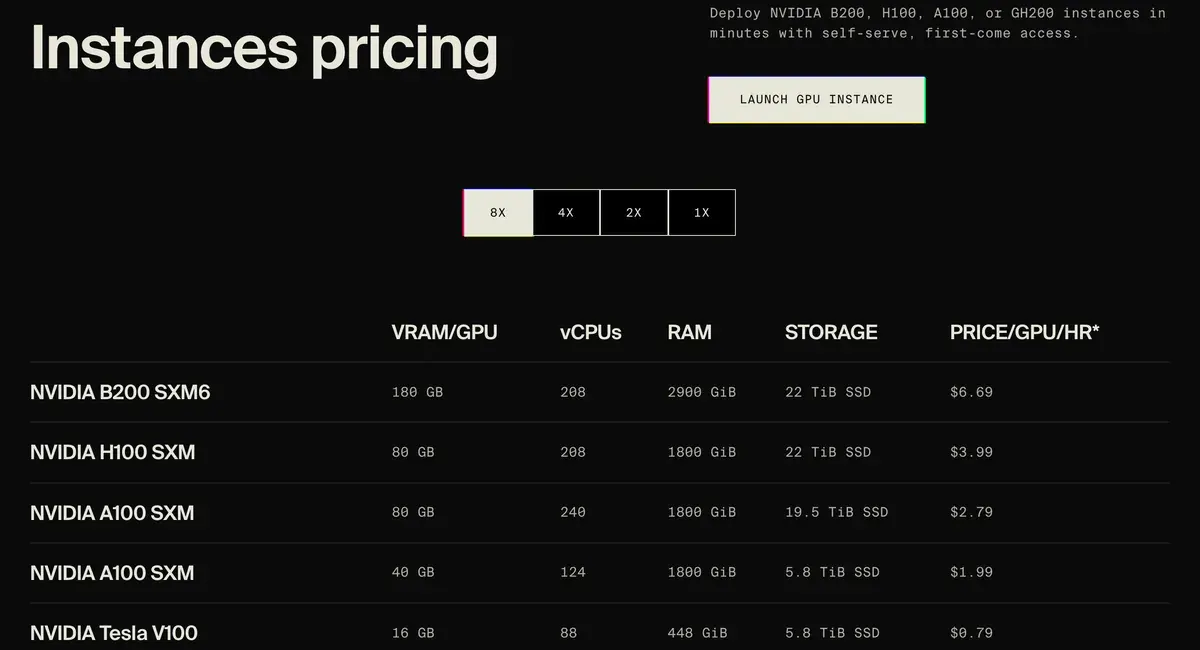
Commitment is the second lever. Paperspace shows an A100 at $1.15 an hour, and only on a three-year term. Lambda prices its A100 SXM 80 GB only in machines of eight cards, at $2.79 per card.
Serverless costs more per hour and less per month when requests are rare. Runpod’s flex worker bills from start to full stop and scales to zero between jobs (Runpod pricing). Modal bills each second a function runs, with no charge between requests: its H100 rate of $0.0011 a second is $3.95 an hour (Modal pricing).
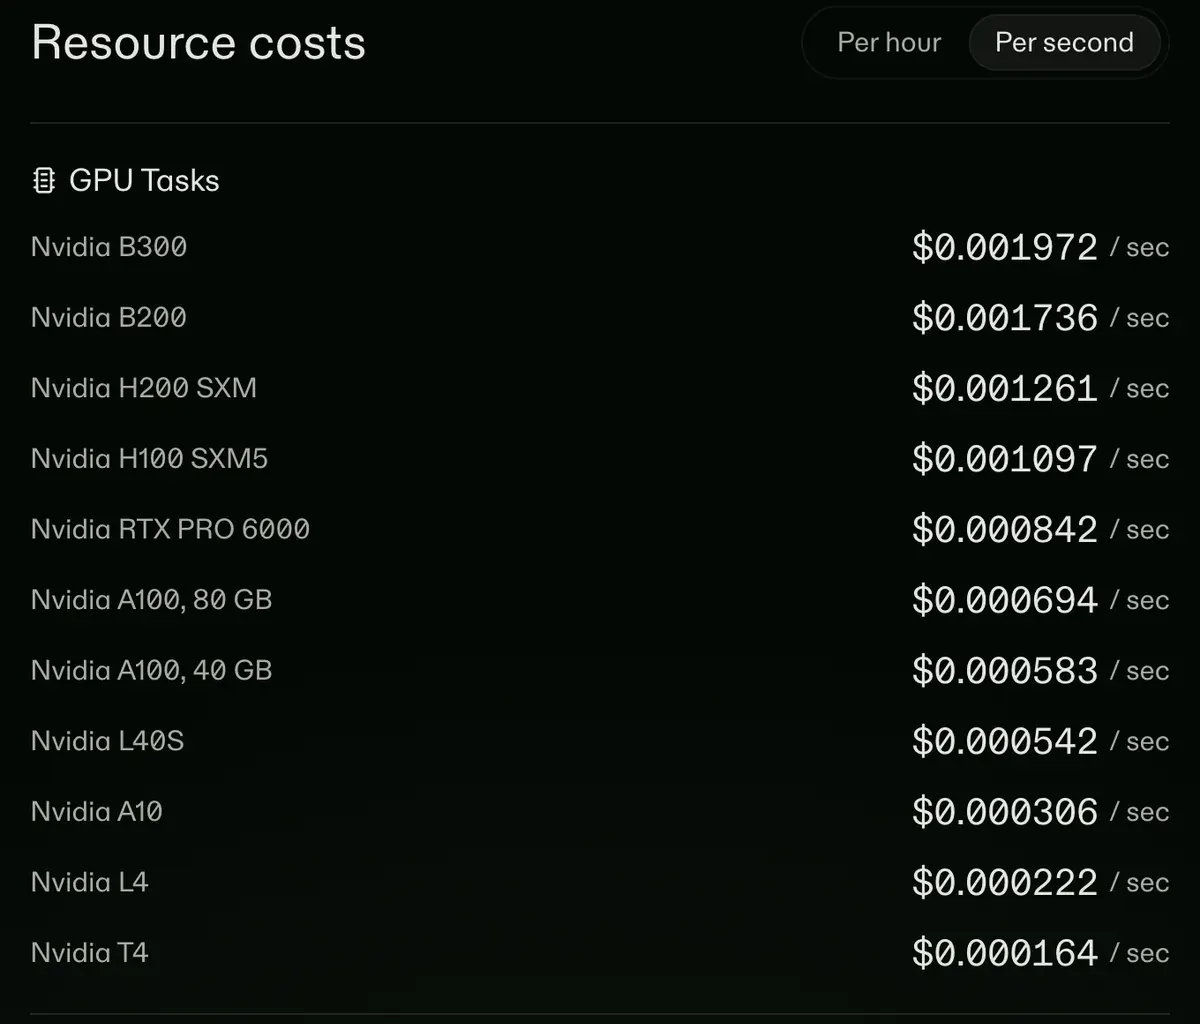
What one image or clip costs
Price per hour tells you little until you know how fast the card works. The useful figure is cost per output: the hourly price divided by the outputs you finish in an hour.
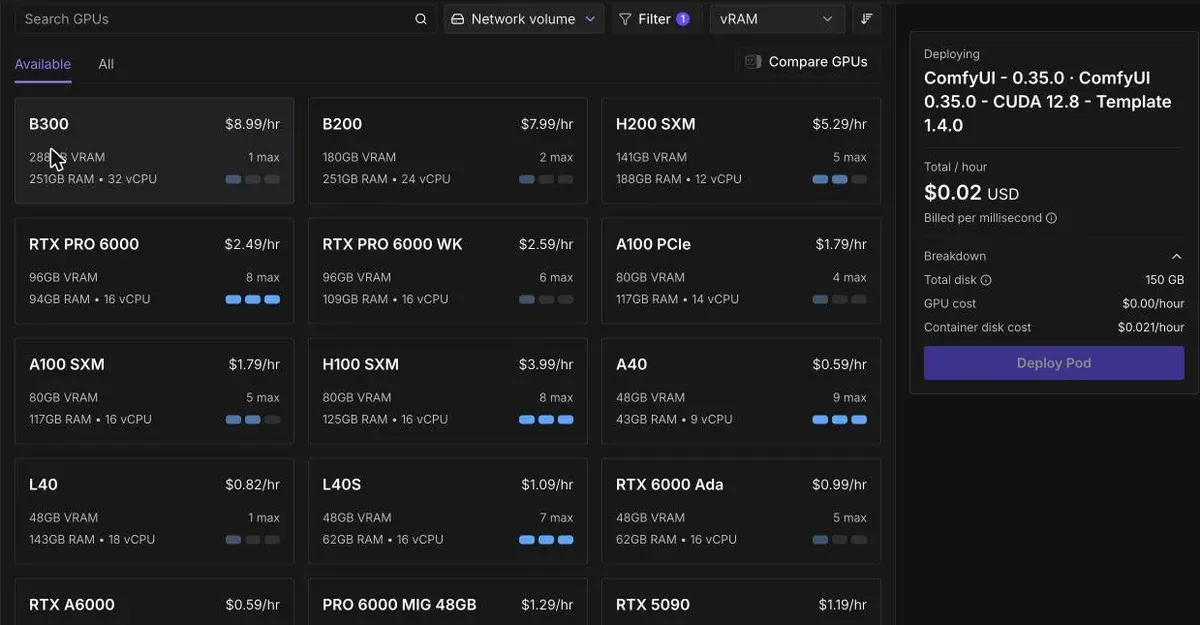
On our own Runpod account on 17 October 2026, an RTX 4090 on Secure Cloud made 12 FLUX 3 Klein images in 342 seconds. Each was 1280 x 1280 at 16 steps, about 28.5 seconds an image.
The table below applies that time to each 4090 rate. Every row assumes the 28.5 seconds measured on Secure Cloud.
| Where the 4090 runs | Per hour | Per 100 images |
|---|---|---|
| Runpod Community Cloud | $0.34 | $0.27 |
| TensorDock, typical price | $0.35 | $0.28 |
| Vast.ai, lowest verified | $0.41 | $0.32 |
| Runpod Secure Cloud, measured | $0.89 | $0.70 |
| Runpod Serverless | $1.10 | $0.87 |
Scroll sideways for all 3 columns
The settings change the bill more than the cloud does. The full FLUX 3 Klein model at 50 steps took about 4 minutes an image on the same pod, $0.06 each.
These figures are GPU time only. Starting the pod, loading the model and storage come on top. Our Runpod pricing breakdown adds those up.
For video, time one clip on your own pod and divide. Runpod’s own hosted Wan 2.2 makes a 5-second 720p clip for $0.30 (Runpod pricing). A rented 5090 at $1.19 beats that only if each clip takes under 15 minutes (1.19 divided by 0.30 is 3.97 clips an hour).
Which GPU for which job
VRAM is the first filter. A model that does not fit spills into the computer’s main memory (offloading), which works but runs slower.
| Job | VRAM it needs | Cards that fit |
|---|---|---|
| Ad stills with FLUX or similar image models | Models of 6 to 17 GB, on our own Runpod account | RTX 4090 or 5090 |
| Wan 2.2 5B video | Fits 8 GB with ComfyUI’s offloading, per ComfyUI’s docs | Any card in the table; RTX 4090 cheapest |
| Large video models near 40 GB | More than a 5090’s 32 GB, on our own Runpod account | L40S, A100 or RTX PRO 6000 |
Scroll sideways for all 3 columns
A video model of about 40 GB overflows a 5090 and offloads. On our own account, that overflow is why a 96 GB card can cost less per clip despite its higher hourly price. Wan 2.2’s model card says its 5B version “can also run on consumer-grade graphics cards like 4090” (Hugging Face).
Step-by-step setups are in Wan 2.2 on Runpod with ComfyUI and ComfyUI on Runpod. Our Runpod hub gathers the rest.
The model’s licence goes with every rental
The cloud rents hardware; the model’s licence decides whether its output can run in an ad. Wan 2.2 is Apache 2.0. LTX-2 needs a paid licence once a company earns $10,000,000 a year or more (licence, section 2.1).
MiniMax H3’s licence excludes the US, the EU, the UK and South Korea, so its clips cannot run as ads there whichever GPU made them. Cheaper hosts for the same work are compared in Runpod alternatives.
How the table is built
A price enters the table when the provider’s own page or API shows it, for one card on demand, read on 24 October 2026. “Not listed” means that page shows no single-card on-demand price for that GPU.
Vast.ai prices come from its public offer search: verified, rentable, single-GPU, on-demand offers, sorted by total hourly price with the default disk. Modal publishes rates per second; the table multiplies them by 3,600. TensorDock’s page gives a typical price that varies by host and says it was last updated on 24 July 2024.
Each row keeps an anchor, so a link such as /data/cloud-gpu-prices/#runpod-community stays stable. Corrections show in this page’s list of changes and on updates and corrections.
How to cite this data
adtestbench, "Cloud GPU prices for AI images and video", https://adtestbench.com/data/cloud-gpu-prices/, updated .
- CSV file /data/cloud-gpu-prices.csv
Sources
- Runpod: Runpod pricing, Secure Cloud, Community Cloud and Serverless rates; the GPU-type API on our own account gave the same figures. Checked
- Vast.ai: Vast.ai offer search API, verified, rentable, single-GPU on-demand offers; the total hourly price includes the default disk. Checked
- Vast.ai: Vast.ai pricing, prices set by hosts. Checked
- Lambda: Lambda GPU cloud pricing, price per GPU per hour, billed by the minute, plus sales tax or VAT. Checked
- Modal: Modal pricing, GPU rates per second. Checked
- TensorDock: TensorDock cloud GPUs, typical hourly price, varies by host, billed per second; page last updated 24 July 2024. Checked
- Massed Compute: Massed Compute pricing. Checked
- DigitalOcean: DigitalOcean GPU Droplets pricing, billed per second, 5-minute minimum. Checked
- Paperspace (DigitalOcean): Paperspace pricing, H100 on demand at a promo price; A100 rate shown only with a three-year commitment. Checked
- ComfyUI docs: Wan2.2 in ComfyUI, the 5B model and native offloading. Checked
- Runpod docs: Choose a Pod, Community Cloud reliability Variable; no new Community hosts. Checked
- Wan-AI on Hugging Face: Wan2.2 TI2V-5B model card, Apache 2.0; runs on consumer-grade cards such as the 4090. Checked
- Lightricks on GitHub: LTX-2 Community License Agreement, section 2.1. Checked

Alexandre S.
Alexandre S. is a creative ad strategist and copywriter with ten years' experience in digital marketing across multiple channels.
Related pages
-
 Data AI ad tool price tracker
69 of 82 AI ad tools show a list price read on the vendor’s own page, last checked 16 October 2026, with the cost per clip or image where a rate allows.
-
 Guide AI influencer ComfyUI workflow
The ComfyUI blocks behind an AI influencer, each open model’s licence, where to find workflows and the rented GPU cost per image. Checked 24 Oct 2026.
-
 Pricing Higgsfield pricing
Higgsfield plans start at $19 a month for 270 credits, about $0.07 a credit. What Unlimited covers, the free plan, the trial and refunds. Checked 25 Oct 2026.


