Runpod alternatives
Verdict on Runpod alternatives
Stay on Runpod for ComfyUI on a 4090: Vast.ai’s cheapest verified 4090 costs $0.41 an hour against Runpod’s $0.34. On a 5090, Vast.ai’s cheapest verified host is $0.05 an hour cheaper (read ).
The catch is availability: 13 of 48 user sources report popular GPUs they could not get (Trustpilot, Reddit).
For ComfyUI on a rented RTX 4090 or 5090, with models kept between sessions: Runpod
Official ComfyUI template, models on a network volume. On our own Runpod account on 17 Oct 2026, a FLUX image took 28.5 s on a Secure Cloud 4090.
For ad video and images with no GPU, model or workflow to set up:  Higgsfield
Kling, Veo and Seedance in the browser on one credit balance; you pay per generation, never per hour.
| Tool | Monthly from (USD) | Checked | What it does | Official site |
|---|---|---|---|---|
| Runpod The tool you are replacing | Pay per use | GPU cloud billed by the second: rent an RTX 4090 from $0.34 an hour and run ComfyUI, Wan 2.2, LTX-2 or FLUX yourself. | Visit Runpod | |
 Higgsfield | $15 | Multi-model studio with Seedance, Kling, Veo and its own Soul models, plus ad and UGC tools and an agent. | Visit Higgsfield |
Scroll sideways for all 5 columns
Why people look for a Runpod alternative
A GPU is the graphics chip that runs image and video models, and VRAM is its own memory: the model has to fit in it. Runpod rents both by the hour. You start a pod (a rented machine with one or more GPUs), from a template (a ready-made software setup such as ComfyUI). Our Runpod hub covers the whole route.
Our count rests on 48 user sources. They are the 24 reviews on the first page of Runpod’s Trustpilot listing and 24 Reddit threads from February to October 2026.
Availability leads the complaints: 13 of 48 sources report popular GPUs they could not get (Trustpilot, Reddit). Eight describe pods that never worked or launches that failed (Trustpilot, Reddit).
Price is the second reason: 7 of 48 sources describe price rises on the RTX 5090 and 4090, or call the service expensive (Reddit, Trustpilot).
The praise is about setup. Five of 48 sources find Runpod easy to set up, and 3 praise quick answers from support (Trustpilot). Four of 48 value renting a high-end GPU by the second (Trustpilot, Reddit).
Hourly prices for an RTX 4090, 5090 and H100
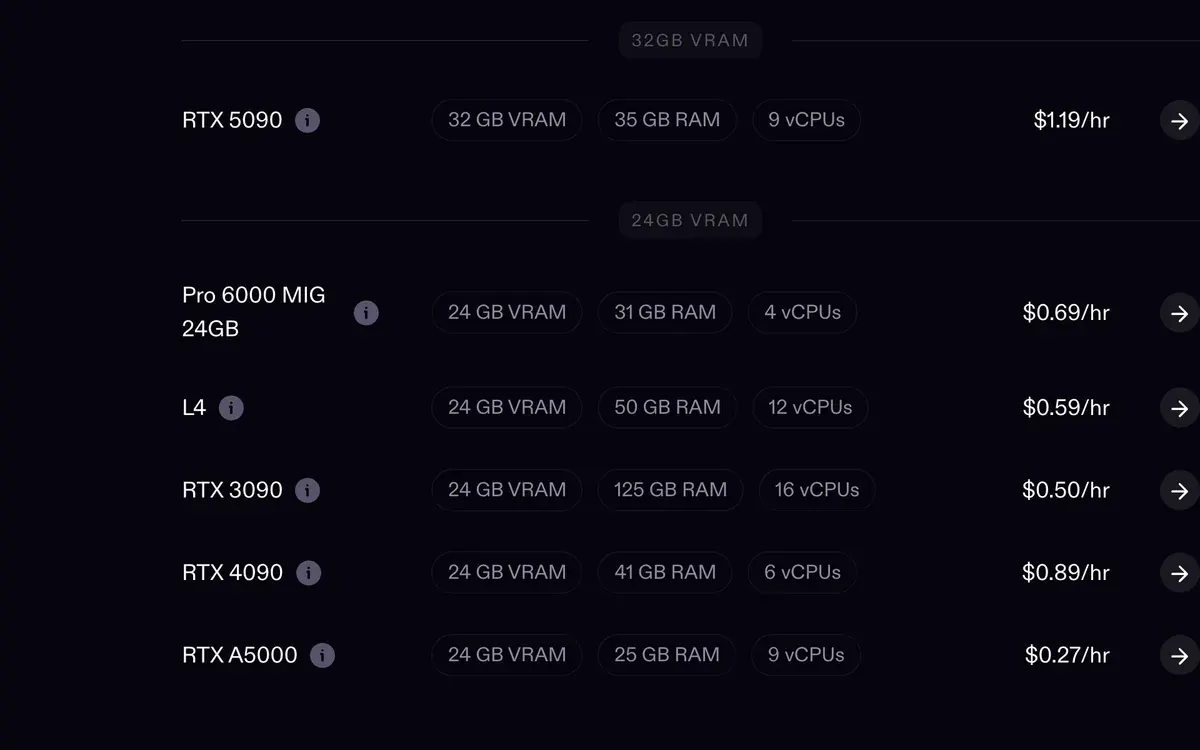
Runpod’s Community Cloud lists the lowest RTX 4090 rate, and the lowest H100 by one cent. Vast.ai’s verified hosts list the lowest RTX 5090. For Vast.ai the table counts verified hosts only, and every price comes from the vendor’s own page or API on 24 October 2026.
| Cloud and tier | RTX 4090 (24 GB) | RTX 5090 (32 GB) | H100 (80 GB) |
|---|---|---|---|
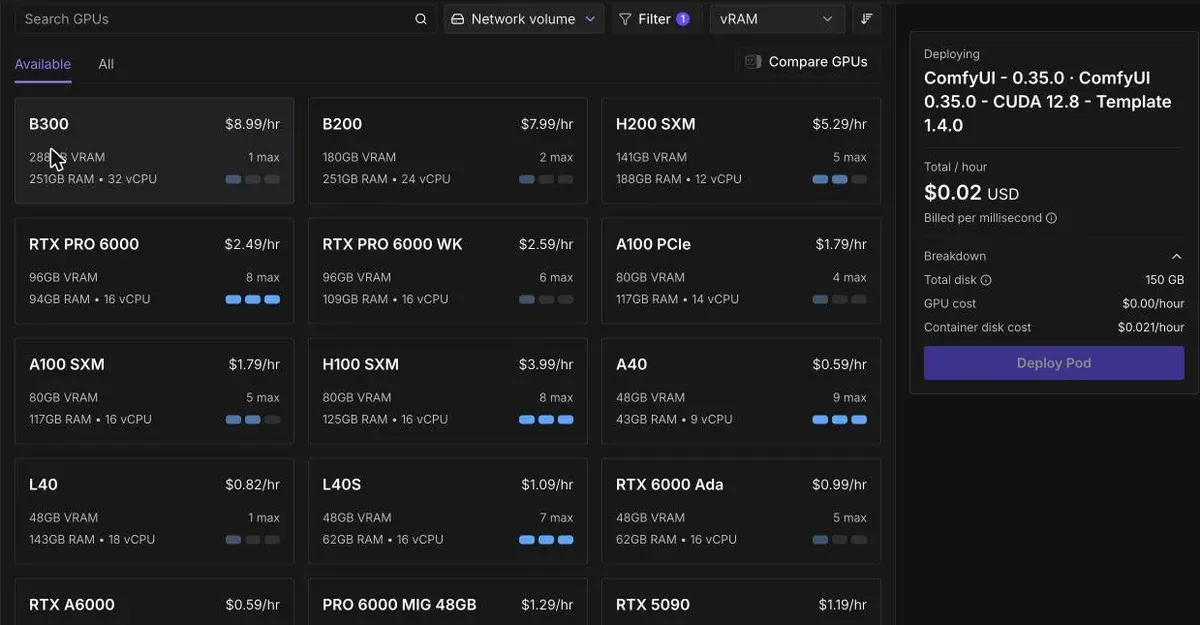
| Runpod Community H100 PCIe, billed by the second | $0.34 | $0.69 | $1.99 |
| Runpod Secure H100 PCIe, billed by the second | $0.89 | $1.19 | $2.89 |
| Vast.ai Lowest verified offer, H100 PCIe | $0.41 | $0.64 | $2.00 |
| TensorDock Typical price, varies by host; H100 SXM5, billed per second | $0.35 | Not listed | $2.25 |
| Massed Compute H100 80 GB, priced by the hour | Not listed | Not listed | $2.73 |
| Lambda H100 PCIe, billed by the minute | Not listed | Not listed | $3.29 |
| Modal H100 SXM5, billed per second | Not listed | Not listed | $3.95 |
| DigitalOcean GPU Droplets HGX H100, per second, 5-minute minimum | Not listed | Not listed | $4.41 |
| Paperspace H100 on demand at a promo rate, billed per hour | Not listed | Not listed | $5.95 |
Scroll sideways for all 4 columns
The cheapest row is not always the cheapest image. A slower card at a lower rate can cost more per output. Divide the hourly price by the outputs you get in an hour before you switch.
Runpod vs Vast.ai: the same cards, two kinds of host
Vast.ai is a marketplace: independent hosts list their own machines and set their own prices. Its pricing page says prices “are set by the market, not by Vast.” Runpod lists one price per card for its Secure Cloud and another for its Community Cloud of peer-to-peer hosts.
Vast.ai’s offer search on 24 October 2026 returned 39 verified RTX 4090 machines for one GPU on demand. The cheapest was $0.41 an hour and the middle one $0.67. Unverified hosts listed lower, from $0.17.
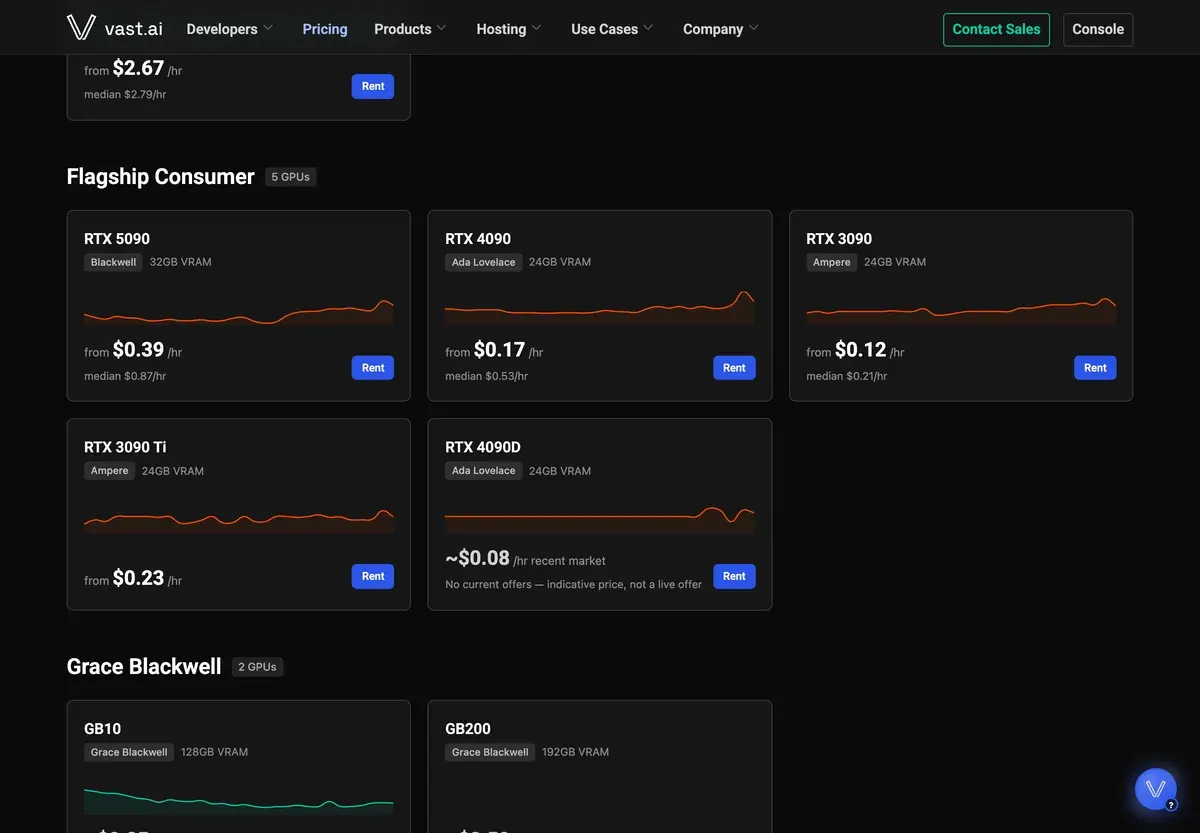
Vast.ai also sells Interruptible machines, which its pricing page says “may be reclaimed.” That suits a batch of stills you can restart. It hurts a 20-minute video render.
On Trustpilot, Vast.ai has 262 reviews and a TrustScore of 3.8, against 387 reviews and a TrustScore of 3.5 for Runpod. Both were read on 24 October 2026.
Both clouds run ComfyUI from a template. Vast.ai’s video generation guide finds it by searching “ComfyUI” in the Templates tab. Runpod’s template picker shows the official ComfyUI template first, with community templates for Wan 2.2 beside it.
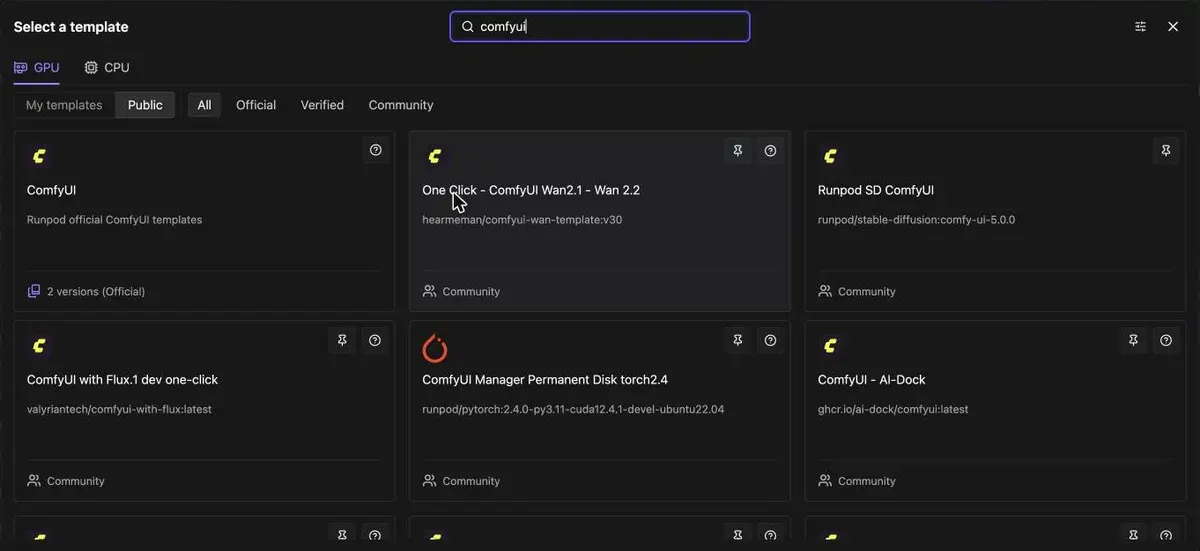
Runpod keeps your models on a network volume, storage that outlives any one pod. On our own Runpod account, 28 short pod sessions between 16 and 21 October 2026 cost $9.26 in total.
Network storage for the models added $2.21 over October to the 24th, the one cost that runs while no pod does. Our Runpod pricing page breaks the bill down, and ComfyUI on Runpod walks through the setup.
A new Runpod user who signs up with Google through a referral link, then loads $10, gets a one-time credit. So does the person who referred them.
The credit runs from $5 to $500, and most people get $5 (referral docs). Users in Europe get a flat $5. Our Runpod referral code guide covers the steps.
Modal: GPUs by the second from Python code
Modal runs your Python function on a GPU and bills each second it runs, so a setup waiting between requests costs nothing. That suits a team turning one ComfyUI workflow into an API for an ad tool. Modal’s docs show a ComfyUI workspace started with one command, modal serve.
Modal lists data-centre cards only. Its H100 works out at $3.95 an hour and its L40S at $1.95, against Runpod Secure Cloud’s $1.09 for the same L40S (Modal pricing).
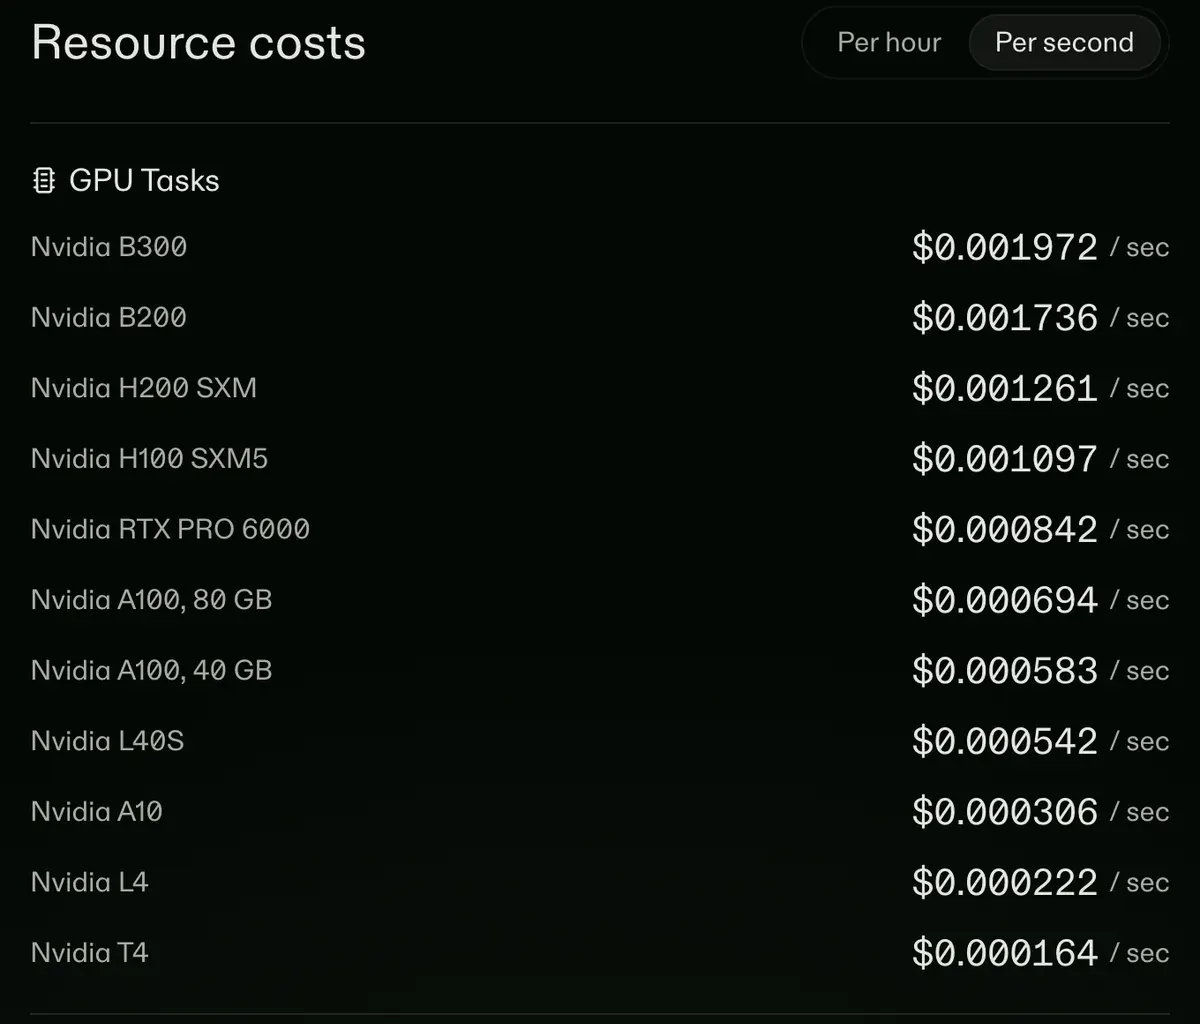
The free Starter plan includes $30 of compute credits a month. Choose Modal if you write code and want nothing running between requests.
Lambda: H100 and B200 for training-size jobs
Lambda rents data-centre GPUs by the minute, from a single card to clusters of eight. One H100 PCIe costs $3.29 an hour and one B200 $6.99.
Its cheapest 24 GB card is a Quadro RTX 6000 at $0.69, two generations older than a 4090. Lambda fits training a model on eight GPUs at once. For one person making stills, the 4090 rates above cost less.
TensorDock: marketplace prices with a stale page
TensorDock is a marketplace like Vast.ai. Its public page gives a typical hourly price of $0.35 for an RTX 4090 and $2.25 for an H100 SXM5, billed per second.
The same page says the price “varies by host” and that it was last updated on 24 July 2024. Live rates sit behind its dashboard.
Massed Compute: fixed hourly rates on 48 to 96 GB cards
Massed Compute prices each GPU machine by the hour. An L40S with 48 GB costs $0.97 and an RTX PRO 6000 Blackwell with 96 GB $2.19.
Runpod’s Community Cloud lists the same RTX PRO 6000 at $1.69. Massed Compute lists no RTX 4090 or 5090, so it suits big video models that need the 96 GB.
Paperspace and DigitalOcean GPU Droplets
Paperspace now belongs to DigitalOcean, whose banner reads “Paperspace is now part of DigitalOcean!” Its pricing page gives an on-demand H100 at $5.95 an hour under a “special promo price”. Its lower H100 and A100 rates require a three-year commitment.
DigitalOcean’s own GPU Droplets list an L40S at $1.57 an hour, billed per second with a 5-minute minimum. A powered-off Droplet keeps billing until you destroy it.
Baseten: models deployed as APIs, priced by the minute
Baseten hosts a model as an endpoint and bills “down to the minute” while it computes. An H100 costs $0.108 a minute, which is $6.50 an hour. Baseten runs and scales the model server for you. On a Runpod pod you run it yourself, and Runpod’s Serverless sits between the two.
Comfy Cloud: ComfyUI in the browser on a monthly plan
Comfy Cloud is ComfyUI run by its own makers, with no pod to start. Standard costs $20 a month and every plan runs on an RTX 6000 Pro with 96 GB.
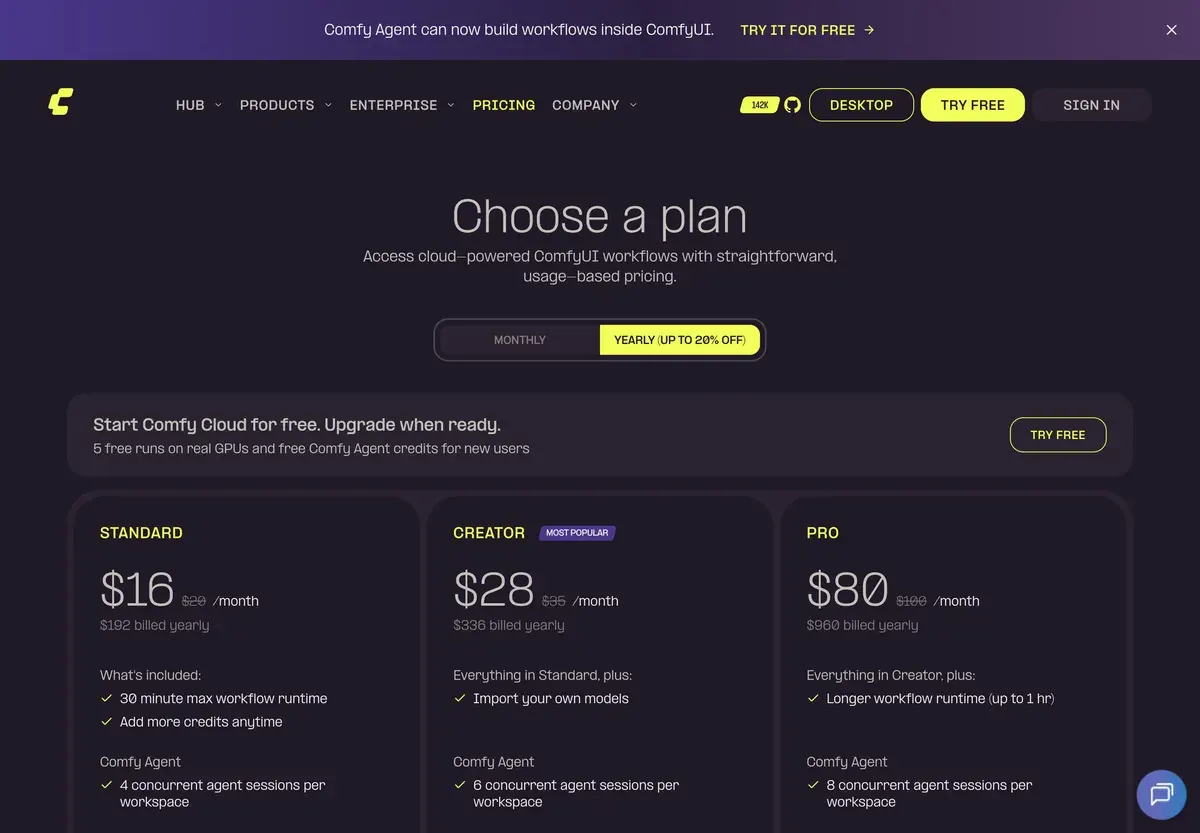
Each job on Standard stops at 30 minutes, and Pro raises that to one hour. Choose it if your jobs finish inside 30 minutes and you would rather pay $20 a month than by the hour.
 Higgsfield: per-credit apps instead of a GPU
Higgsfield sells finished generations from Kling, Veo, Seedance and its own Soul models on one credit plan. Starter costs $15 a month (pricing page, checked ).
You never pick a GPU or load a model. The trade is the model list: open models such as Wan 2.2 or LTX-2 with your own settings need a rented GPU. Our Higgsfield profile covers its credits and terms.
Model licences move with you
Every cloud above rents hardware, so the licence of the model you run decides what your ad may do. Wan 2.2 is Apache 2.0. LTX-2 is free for commercial use below $10,000,000 of yearly revenue (licence, section 2.1).
MiniMax H3’s community licence excludes the US, the EU, the UK and South Korea, so it is no route for ads there on any cloud. Wan 2.2 on Runpod sets up the Apache model step by step.
Left out, and why
Google Cloud, AWS and Azure price GPUs inside whole virtual-machine families, region by region and behind quotas. No single hourly figure from them compares with the rows above.
Sources
- Runpod: Runpod pricing, Secure Cloud, Community Cloud and Serverless rates per hour; our own account’s API gave the same rates. Checked
- Runpod docs: Runpod referral programme, Google sign-up, a minimum first load, a one-time credit for both people. Checked
- Vast.ai: Vast.ai pricing, prices set by hosts; On-Demand, Interruptible and Reserved tiers. Checked
- Vast.ai: Vast.ai offer search API, verified, rentable, single-GPU on-demand offers sorted by total hourly price. Checked
- Vast.ai docs: Vast.ai video generation guide, the ComfyUI template in the Templates tab. Checked
- Modal: Modal pricing, GPU rates per second; free monthly credits on Starter. Checked
- Modal docs: Run ComfyUI on Modal. Checked
- Lambda: Lambda GPU cloud pricing, on-demand price per GPU per hour, billed by the minute. Checked
- TensorDock: TensorDock cloud GPUs, typical hourly price, varies by host, billed per second; the page says it was last updated 24 July 2024. Checked
- Massed Compute: Massed Compute pricing. Checked
- Paperspace (DigitalOcean): Paperspace pricing, H100 on demand at a promo rate; other rates shown are three-year commitments. Checked
- DigitalOcean: DigitalOcean GPU Droplets pricing, billed per second with a 5-minute minimum. Checked
- Baseten: Baseten pricing, dedicated deployments priced per minute. Checked
- Comfy Org: Comfy Cloud pricing, four plans on an RTX 6000 Pro with 96 GB; 30 minutes a job on Standard. Checked
- Trustpilot: Runpod reviews, 387 reviews, TrustScore 3.5; findings counted on the 24 reviews on the first page. Checked
- Reddit, read through the Arctic Shift archive: Runpod threads on r/RunPod and r/comfyui, 24 threads, February to October 2026. Checked
- Trustpilot: Vast.ai reviews, 262 reviews, TrustScore 3.8. Checked
- MiniMax on Hugging Face: MiniMax H3 Community License Agreement, Excluded Territories. Checked
- Lightricks on GitHub: LTX-2 Community License Agreement, section 2.1, a paid licence above a yearly revenue line. Checked

Alexandre S.
Alexandre S. is a creative ad strategist and copywriter with ten years' experience in digital marketing across multiple channels.
Related pages
-
 Category Best AI video generators for ads
23 AI video generators and model shops compared on cost per clip and ad-use terms, checked 25 September 2026.
-
 Profile Runpod
Runpod for ad images and video: Secure or Community Cloud, Pods or Serverless, model licences, and what 48 user sources report. Checked 24 Oct 2026.
-
 Pricing Runpod pricing
Runpod GPU prices per hour on Secure, Community and Serverless, storage rates and what one image costs on our own RTX 4090 Pod. Checked 24 Oct 2026.
-
 Guide AI influencer ComfyUI workflow
The ComfyUI blocks behind an AI influencer, each open model’s licence, where to find workflows and the rented GPU cost per image. Checked 24 Oct 2026.
-
 Alternatives Higgsfield alternatives
Other studios that resell Kling, Veo and Seedance on one plan, set against Higgsfield on cost per clip, training terms and refunds, checked 2 October 2026.
-
 Data AI ad tool price tracker
69 of 82 AI ad tools show a list price read on the vendor’s own page, last checked 16 October 2026, with the cost per clip or image where a rate allows.


